No Two Mondays: Trial Period / modvar
Engineering No Two Mondays:
An extensible simulation with AI.
How I used AI-assisted development to build an office narrative game, applying human judgment and engineering expertise to turn repeated feedback into a system I could keep extending.
Content last revised:
Executive summary / Independent engineering project
Engineering at a Glance
- Challenge
- Build an extensible office simulation where technical work, conversations and spatial interactions have connected consequences.
- Role
- I directed the product and architecture, set engineering constraints, reviewed AI-assisted implementation and iterated through playtesting.
- Architecture
- A TypeScript simulation owns state; React presents the interface and Phaser handles spatial presentation. Validated saves, migrations and headless verification support change. Inspect the boundaries.
- Engineering decisions
- Separate state ownership from rendering, reproduce recorded actions deterministically, preserve supported historical saves and require evidence for each bounded iteration. Review the workflow.
- Verification
- The 15 October 2026 campaign against the recorded 0.3.0-rc.1 / monday-8 snapshot verified 112,402 completed simulation runs and independently replayed 8,050 retained artifacts. It verified 44 ending targets; two campaign target gaps remained. Read the scope and gaps.
- Limitations
- Historical campaign figures are not current game-wide totals or evidence of the hosted build. Automated traversal does not establish human understanding, enjoyment, browser accessibility or production infrastructure scale. Check the evidence sources.
Architecture
Give each layer a clear responsibility.
The game uses TypeScript, React, Phaser 3 and Vite. Its simulation owns the world state and publishes snapshots. React subscribes to those snapshots for interface updates; Phaser handles spatial presentation and traversal. A bridge carries room, proximity and interaction signals between the office and the interface.
This boundary lets the simulation run without rendering the office. It supports deterministic tests, automated traversal and save-restoration checks, while interface and artwork changes can be inspected separately. Shared state still needs care: the main simulation runtime coordinates many systems, and adding a module is not free of integration work.
Diagram 03 / Runtime responsibilities
React interface
Menus, reading, feedback and player actions
Phaser office
Rooms, movement and spatial interaction
Room and interaction signals pass through the GameBridge
Actions in ↓ / State snapshots out ↑
TypeScript simulation runtime
State transitions · authored rules · seeded randomness · consequence records
Persistence
Validated snapshots, migrations and local archives
Headless verification
Tests, traversal and independent replay
Extend content through explicit rules
Authored registries, typed actions and state predicates give new content a defined integration point. The event Director filters and scores authored possibilities; it is not a runtime language model inventing the story.
Seeded randomness makes a recorded sequence reproducible under matching code and settings. That is useful for debugging; it does not make the whole possibility space exhaustively tested.
Keep optional work out of startup
The game defers Phaser, optional panels and other modules. Bundle checks inspect the startup graph and enforce size budgets, including keeping the analytics SDK outside startup until optional consent.
These controls make growth measurable. They do not establish a universal frame-rate or mobile performance guarantee.
Preserve progress while the system evolves
Save loading validates the record and applies explicit incremental migrations. Supported historical saves receive conservative defaults; loading restores a snapshot without replaying gameplay. Original bytes are retained before browser conversion, and unsupported or unreadable records have recovery paths.
Diagram 04 / Save compatibility
- 01
Identify
Check the stored version and supported format.
- 02
Preserve
Retain the original before rewriting.
- 03
Migrate
Apply ordered changes and validate the result.
- 04
Restore
Resume the snapshot without rerunning actions.
Verification
Eight hours of automated exploration.
The latest reviewed completion campaign ran on 15 October 2026 against a recorded 0.3.0-rc.1 / monday-8 source snapshot. Its eight-hour execution budget produced 112,402 completed simulation runs with matching verified receipts and unique run identifiers. The integrity report passed.
The tool used witness-guided exploration through normal simulation actions, with recorded settings and source identity. Of the retained artifacts, 8,050 were independently replayed. A compact suite selected 44 replay witnesses covering 118 observed targets. Those targets mix endings, achievements and challenges; they are not 118 separate stories.
How the CLI turns timelines into reviewable evidence.
The developer-only pnpm ntm:traverse CLI exercises the real simulation through legal inputs. It records the order of decisions and semantic state changes, rather than treating every seed or wording change as a new story. That gives me evidence for deciding which variations deserve a closer playtest and which missing paths need investigation.
Diagram 05 / From story traversal to gameplay review
- 01
Configure
Record source, seed, settings, strategy and resource budgets.
- 02
Explore
Run legal action sequences through the actual simulation.
- 03
Verify
Replay retained traces and check their recorded state witnesses.
- 04
Compare
Group semantic timelines and report diversity, dependencies and gaps.
Timeline variants
Compare ordered, meaningful decisions and state changes. Cosmetic wording and seed-only differences do not create separate route identities.
Essential variations
Inspect distinct verified route families and canonical prerequisites. A frequent event in sampled runs is an association, not proof that the event is necessary.
Blocking states and gaps
Distinguish unmet prerequisites, legitimate refusals and stalled attempts from replay failures or a search that exhausted its budget. An unobserved path is not proven impossible.
Human review → a focused revision or playtest
I can inspect retained timelines, compare counterfactual branches and prioritise suspected bottlenecks. The reports provide investigation leads; they do not rewrite the game or establish that a variation is enjoyable. Any change still needs a clear brief, regression checks and human evaluation.
- 112,402
- completed runs / verified receipts
- 8,050
- independently replayed artifacts
- 44
- replay witnesses in the compact suite
The execution budget elapsed in about 8 hours; final reporting finished afterward. Counts are specific to this campaign and its recorded source snapshot.
Endings found, with their files still sealed.
The latest reviewed crawl verified 44 ending targets. Below are all their public locked titles and the number of newly executed runs that finished in each outcome. The labels describe sealed files; real ending names, conditions and route traces stay private.
Counts reconcile to 112,402 unique, verified completed-run receipts from this campaign. The 40 reused baseline successes are excluded. Targeted exploration and repeated attempts shape this distribution: it is not human-player popularity, natural ending probability, unique storyline count or exhaustive coverage. Achievement awards can overlap within one run and are not added to these ending counts.
Complete ending distribution
Automated crawl / 15 October 2026
112,402 completed runs · 44 locked labels · linear bar scale
Scroll to read all labels. Each run contributes to one final ending; repeated runs of the same route still count as runs.
| Locked title | Campaign status |
|---|---|
| An inconvenient agenda | Known witness, unverified in this campaign |
The campaign ended at its duration budget with two target gaps: the unverified outcome above and its associated achievement. That is an unresolved verification gap, not proof that the outcome is impossible.
Headless traversal does not exercise room collision, visual layout, keyboard focus or whether a person enjoys the pacing. Those need browser checks and human playtests. The 15 October release notes separately record 733 automated tests and a 133-test save-compatibility gate for the prepared release candidate; these are historical release checks, not tests rerun by this case study.
Playtest evidence about player understanding
The crawl records deterministic actions, semantic changes and verification receipts so I can investigate the system’s behaviour. Human playtesting answers different questions: did someone understand the next task, recognise the result of a choice or know why a puzzle attempt failed? The game’s optional analytics is designed to support those questions alongside direct feedback.
| Collected signals | Question for review | Interpretation limit |
|---|---|---|
| Puzzle views, attempts, repeated wrong plans, hints and active time | Does a viewed stage receive an attempt? Where might instructions or feedback need attention? | A long visit or repeated attempt can mean deliberation, difficulty or confusion; the metric alone cannot tell which. |
| Presented events, committed choices, consequence receipts and ordered run context | What did the player encounter, choose and observe before the next decision? | Recorded sequence and linked consequences do not prove that the player noticed or understood them. |
| Run milestones, completions, resumes, replay activity and active/paused timing | Where was a run last observed, and how does a repeat visit differ from an initial run? | Missing completion is not confirmed abandonment. Pauses, later returns, consent changes and delivery gaps matter. |
Gameplay sharing is consent-gated and uses explicit event/property allowlists. Automatic click capture and session replay are disabled in the game’s adapter. Local run records and diagnostic exports serve a separate purpose; a playtest report is copied or downloaded explicitly rather than automatically submitted.
No private player records or live analytics results are published here. These are implemented collection capabilities, not a claim that player behaviour has already established a particular improvement. I still need to inspect the evidence, ask players what they understood and evaluate any revision in context.
Lessons
AI accelerated the work. Expertise guided the decisions.
AI made it practical to move quickly between a feature idea, implementation and a diagnostic tool. My responsibility was to decide what the game should become, recognise where the result fell short and make the next change reviewable. Human involvement mattered at every stage: setting priorities, interpreting feedback and deciding what evidence was sufficient for the question being asked.
The value of domain expertise was in turning observations into durable requirements. Ambiguous choices called for clearer feedback. Evolving systems needed boundaries and save compatibility. Generated artwork needed visual inspection and reliable extraction. Automated traversal could verify recorded behaviour at scale, while pacing, clarity and the experience of playing still needed human evaluation.
Try the Monday for yourself.
The game is available on itch.io. This case study covers development snapshots and does not assert that every reviewed change is in the currently hosted build.
Development history and revision evidence
- 210
- recovered human prompts
- 20
- interactive Codex sessions
- 37
- prompts tagged as corrections or refinement
Historical local audit: 9 October–14 October 2026, cutoff 00:05 MYT. Counts describe recovered records through that cutoff; development continued afterward. How these numbers were counted.
01 / The product problem
A small office. A growing system.
No Two Mondays starts with a simple premise: one working day, three coworkers and a production outage. The challenge was to make decisions feel connected across technical work, conversations and the office around you. The setting could stay compact while the underlying system became richer.
I used Codex throughout development, directing features, playing the results, reporting what felt wrong and asking for focused revisions. My work included setting the product constraints, deciding which changes belonged in the game, and requiring evidence that new work preserved existing behaviour.
Here, scalability means being able to add and revise behaviour without losing consistency, save compatibility or a usable browser experience. This is a client-side game; the project does not demonstrate multiplayer concurrency or backend traffic scaling.
A little office conversation.
I wanted the characters to sound like people carrying their work into an ordinary conversation. These are authored in-game coffee responses, shown as separate excerpts rather than one exchange. They give a taste of the office humour without revealing incident explanations or story outcomes.
“Coffee received. I will resist sending an acknowledgement email.”
“You brought coffee. I had only implemented the empty cup.”
“A cup with no escalation policy. Refreshing.”
02 / Working with AI
The prompt started the work. Human judgment steered it.
Codex accelerated implementation, but each change still needed a human decision about what belonged in the game and whether the result worked. I set the direction, played the results, identified what felt unclear or inconsistent, and turned those observations into focused revisions. Keeping a human in the loop meant shaping the work throughout development: framing the problem, inspecting the result and deciding what needed to change.
Domain expertise made that feedback actionable. Software engineering knowledge helped me translate a feature request into requirements for state ownership, persistence, compatibility and regression checks. Interaction decisions needed a different lens: could a player understand a choice, notice its consequences and navigate the interface comfortably? The useful brief connected the intended experience to the constraints and evidence needed to evaluate it.
Diagram 01 / The development loop
- 01
Direct
Human: define the experience, constraints and acceptance criteria.
- 02
Implement
Codex: implement a bounded change and supporting checks.
- 03
Inspect
Human: play and review the result alongside automated evidence.
- 04
Refine
Human: identify the gap and make the next brief more precise.
What I directed
Product scope, interaction clarity, engineering constraints and acceptance criteria. I judged the results against the intended experience and directed follow-up changes.
What AI accelerated
Implementation, test scaffolding, diagnostic tools, documentation and asset iteration. I used those outputs as material to inspect, test and refine.
03 / The cost of iteration
210 prompts did not mean 210 finished features.
The historical audit recovered 210 deduplicated human prompts across 20 interactive sessions. A union of its bug-fixing, refinement and refactoring tags contains 37 distinct prompts. The project feedback log separately records 21 feedback entries at the time of this review. These are different measures: a feedback entry may summarize several requests, and a prompt may address several concerns.
The tagging is automated and lexical. It describes the requests that were recovered, rather than proving how many code modifications were necessary or how much time each feature took. The audit is a partial historical record, not the total lifetime prompt count.
Diagram 02 / Selected request types
| Observed issue | Engineering response | Why human judgment mattered |
|---|---|---|
| Choices were ambiguous | Named the affected character and added clearer action feedback. | Recognising ambiguity required evaluating the player’s understanding as well as the state change. |
| Too much information at once | Grouped interactions and introduced contextual disclosure. | Interaction judgment helped determine when additional depth became too much information. |
| Menus and reading competed with the game viewport | Contained the game surface and refined keyboard, mouse and internal scrolling. | Browser interaction knowledge turned layout and input problems into explicit acceptance checks. |
| Generated character art needed correction | Retained approved sources, recorded generation provenance and used deterministic extraction and registration. | Visual review and asset requirements determined whether generated artwork was usable in the game. |
| New systems had to preserve earlier progress | Made migration, historical fixtures and recovery paths part of the release requirements. | Engineering judgment made preservation of earlier progress a release requirement. |
Art and animation took repeated correction.
Getting the character art right took several rounds of direction and visual review. I asked for changes to the player’s proportions and facial treatment, then had to preserve that approved likeness across different directions and walking poses. I preferred the original, unnormalised artwork; the generation notes record that preference alongside the extraction and registration requirements.
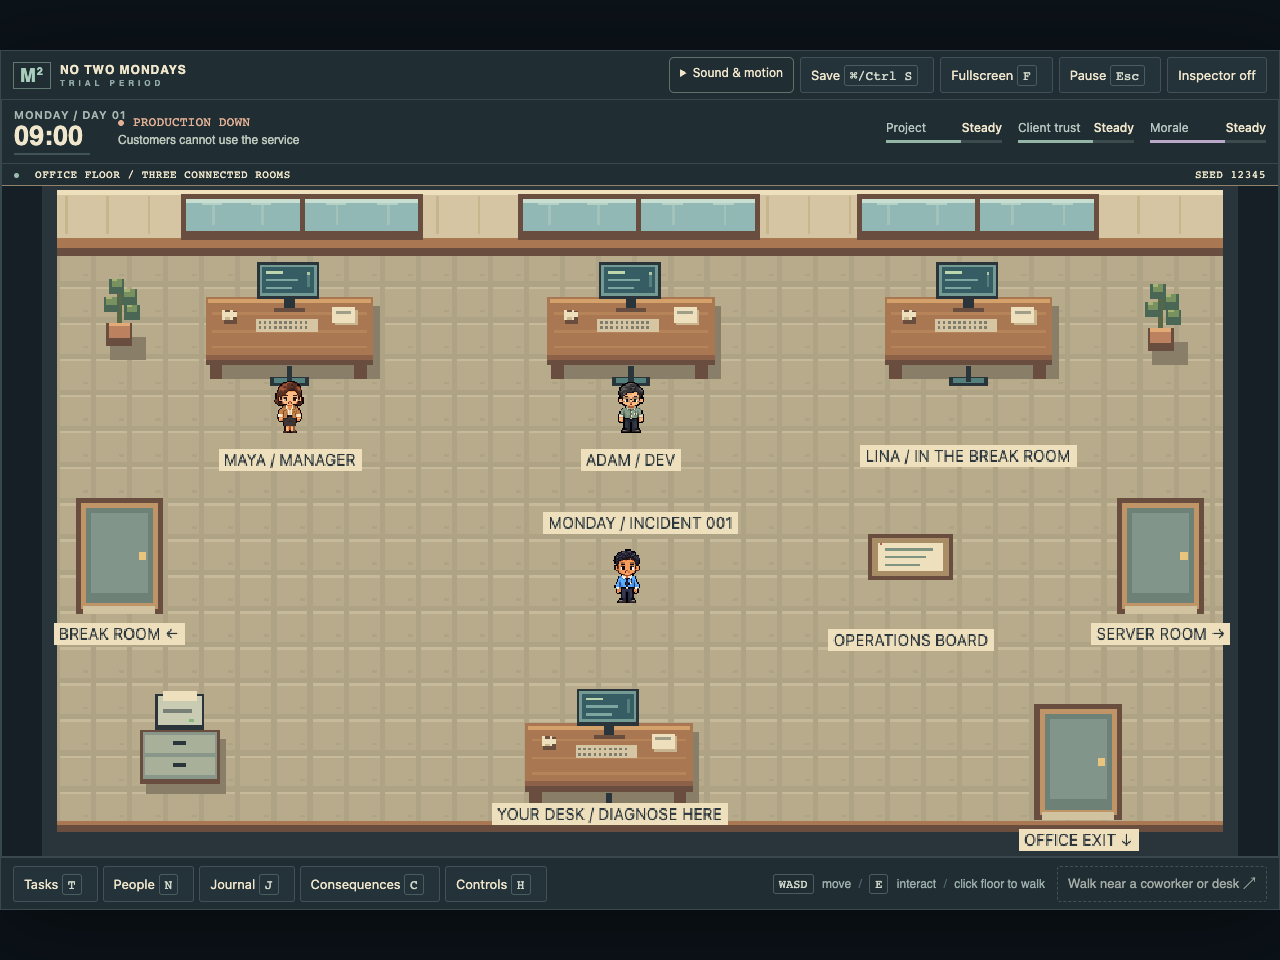
Walking exposed problems that a still image could hide. Equal-sized frame cells did not guarantee equal visible character sizes, and the earlier sequence mixed walking contacts with idle and blink poses. The correction work separated those states, used a uniform scale per character and tied animation to measured movement. A live check also caught gait resets between fixed-step physics updates. These were asset and runtime problems that needed different checks.
The art review still records subtle support-leg differences in some generated poses, including Maya’s front passing frames. Automated bounds, registration and sequence checks could verify parts of the asset contract; they could not establish convincing anatomical motion on their own. I needed to inspect the artwork and movement in the game, and the remaining pose limitations were kept explicit.
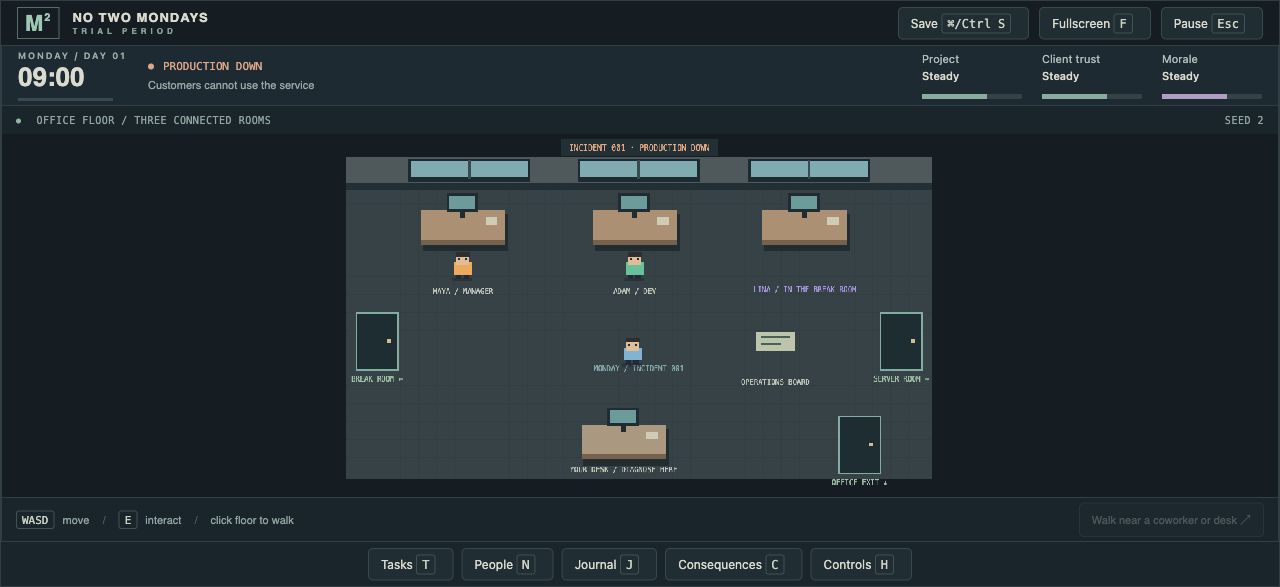
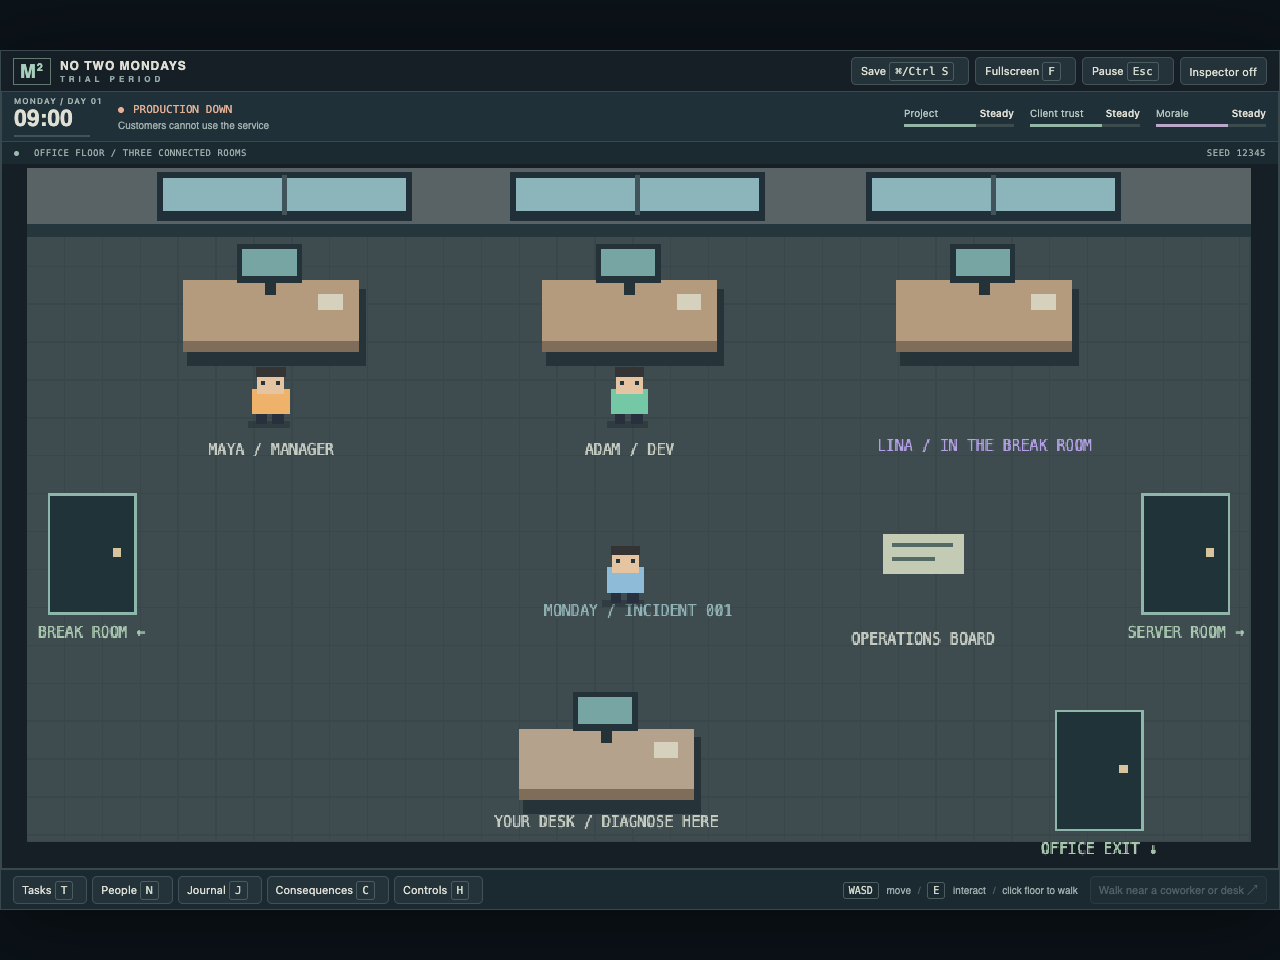
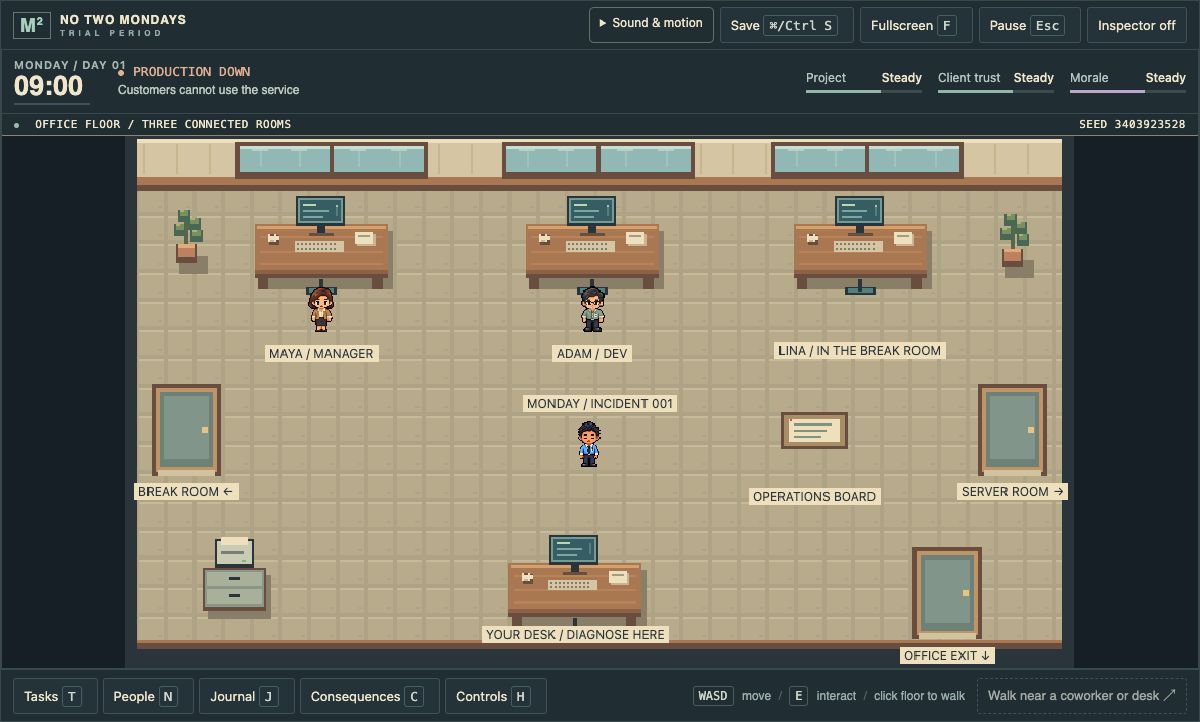
From early visuals to the current build.
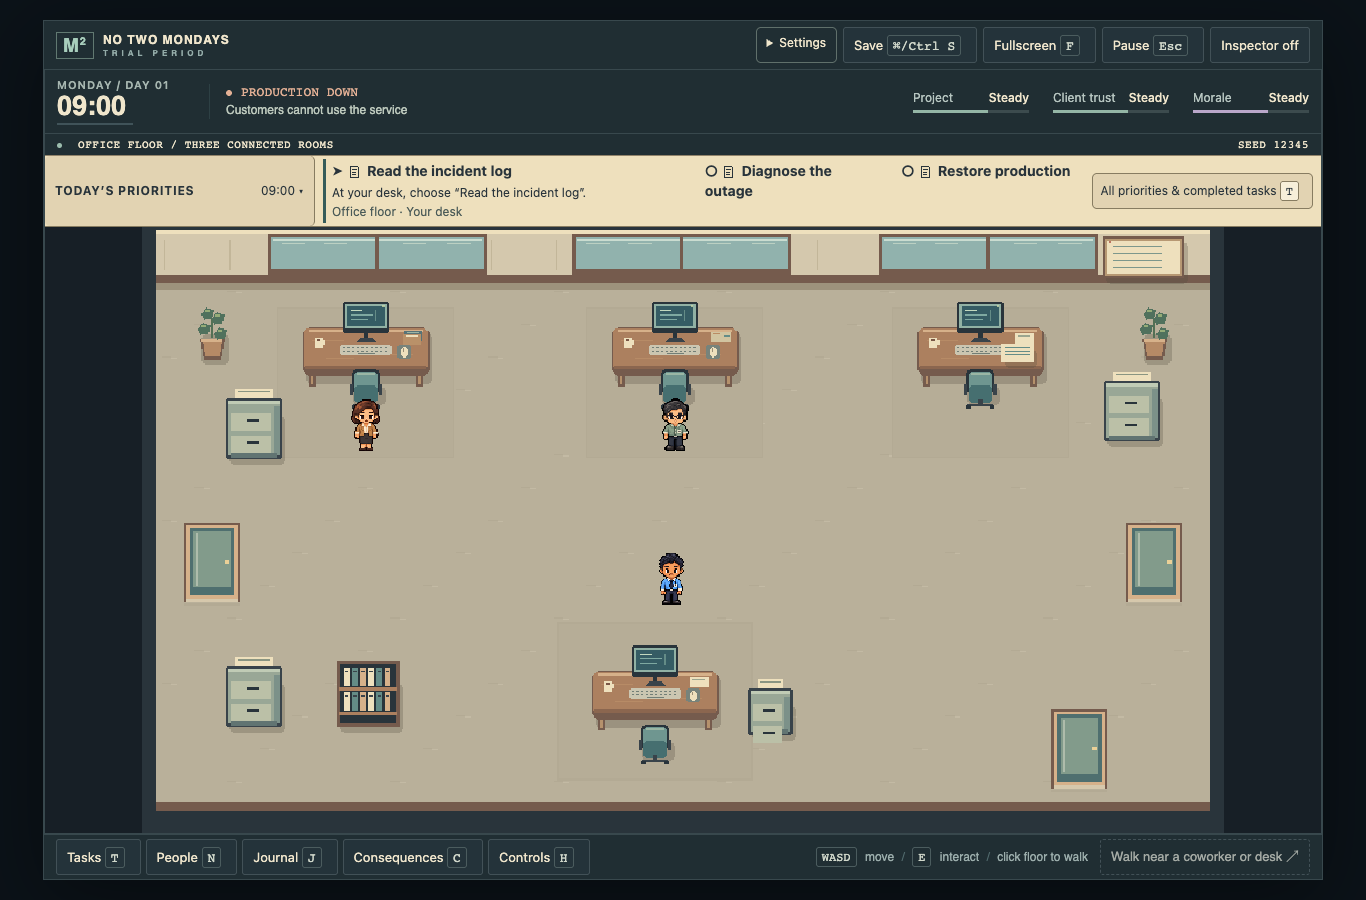
These retained development captures show the early presentation, the character remaster, its sizing/walking correction and the latest reviewed environment redesign. Here, v1–v3 label historical visual milestones, not game release numbers. The latest entry shows the local build captured on 15 October 2026. The captures use different viewport sizes and are not a matched animation comparison. Select an image to inspect the original full-size capture.
v1 / Visual milestone
Early presentation
v2 / Visual milestone
Character remaster
v3 / Visual milestone
Sizing and walking corrections
Latest / Visual milestone
Environment and interaction redesign
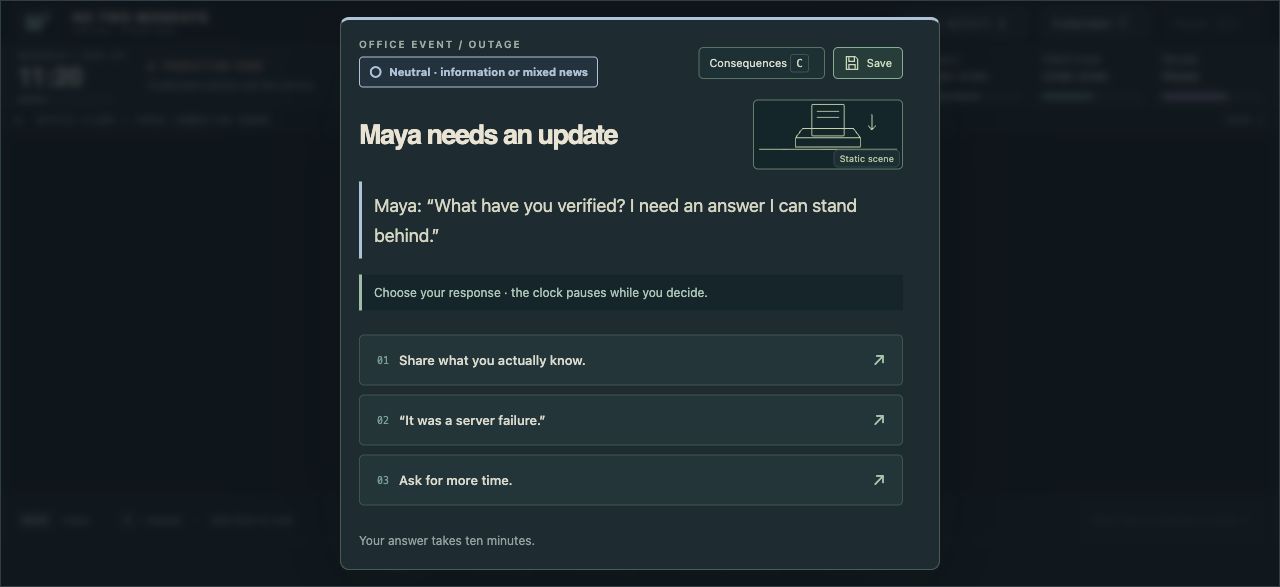
Dialogue UI: from a reply to a decision with context.
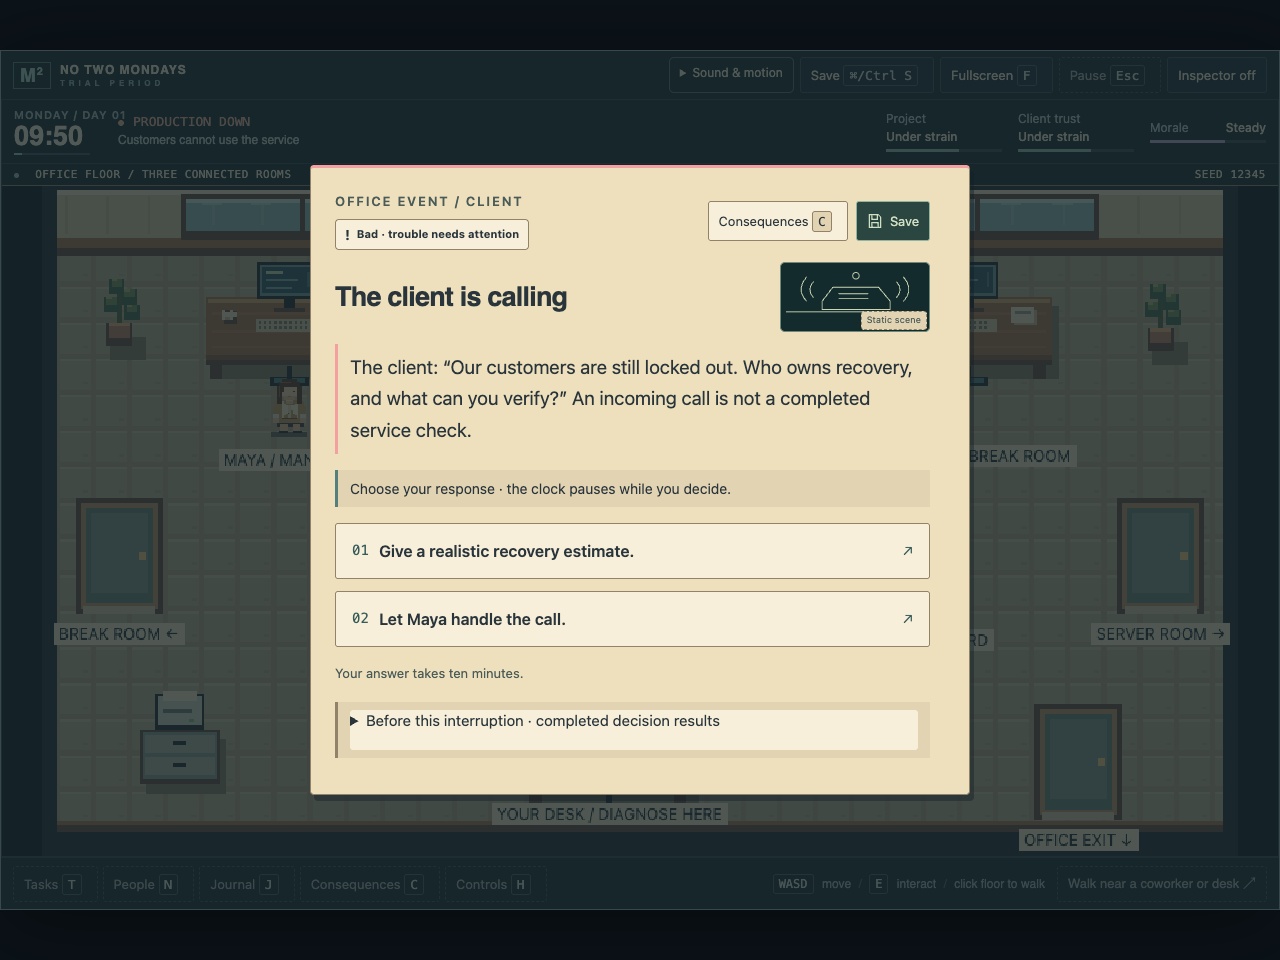
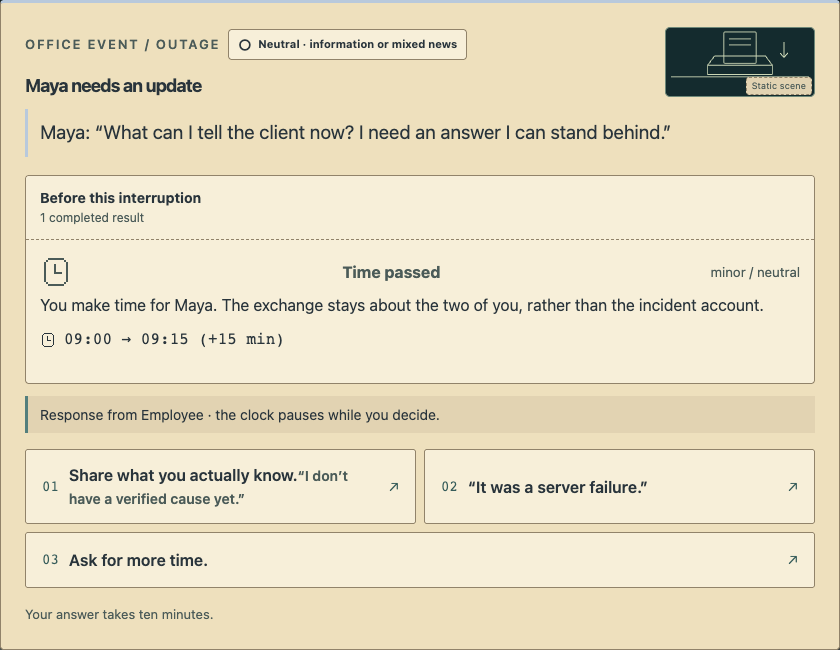
The dialogue interface evolved alongside the feedback system. These selected captures show changes in hierarchy, reading space and the relationship between previous results and the next choice. They show routine office interruptions before a response is chosen; no incident explanation or story outcome is revealed. The latest image was captured from the current source on 15 October 2026.
Early / UI milestone
A focused office update
Paper UI / UI milestone
Stronger document hierarchy
Latest UI / UI milestone
Context before the next decision
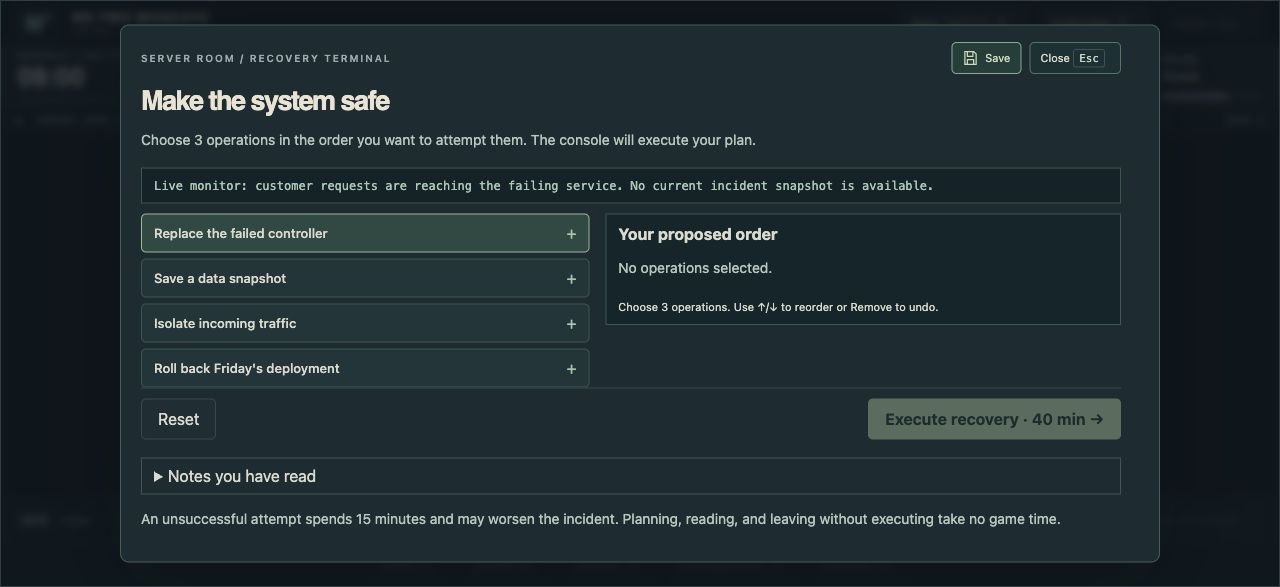
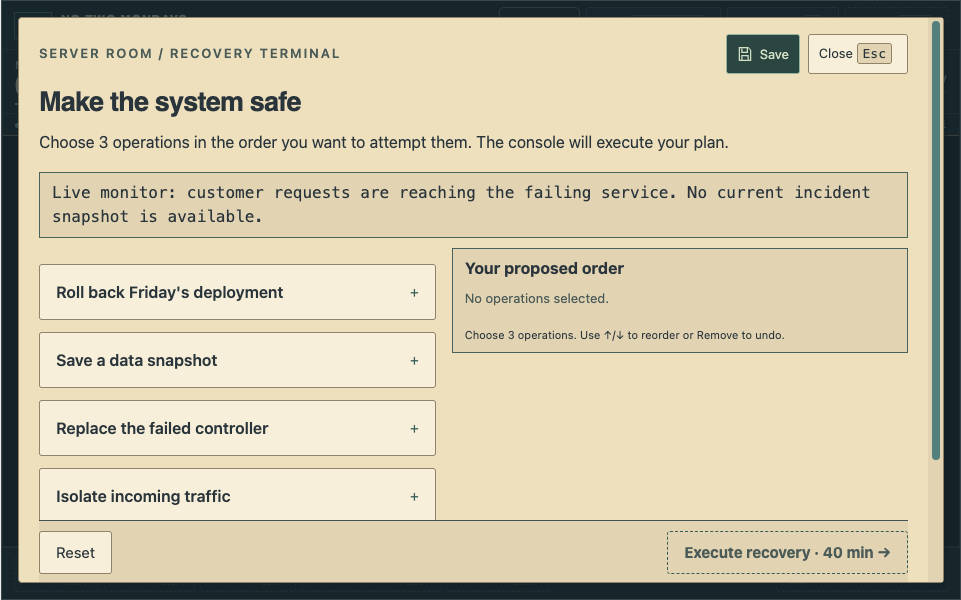
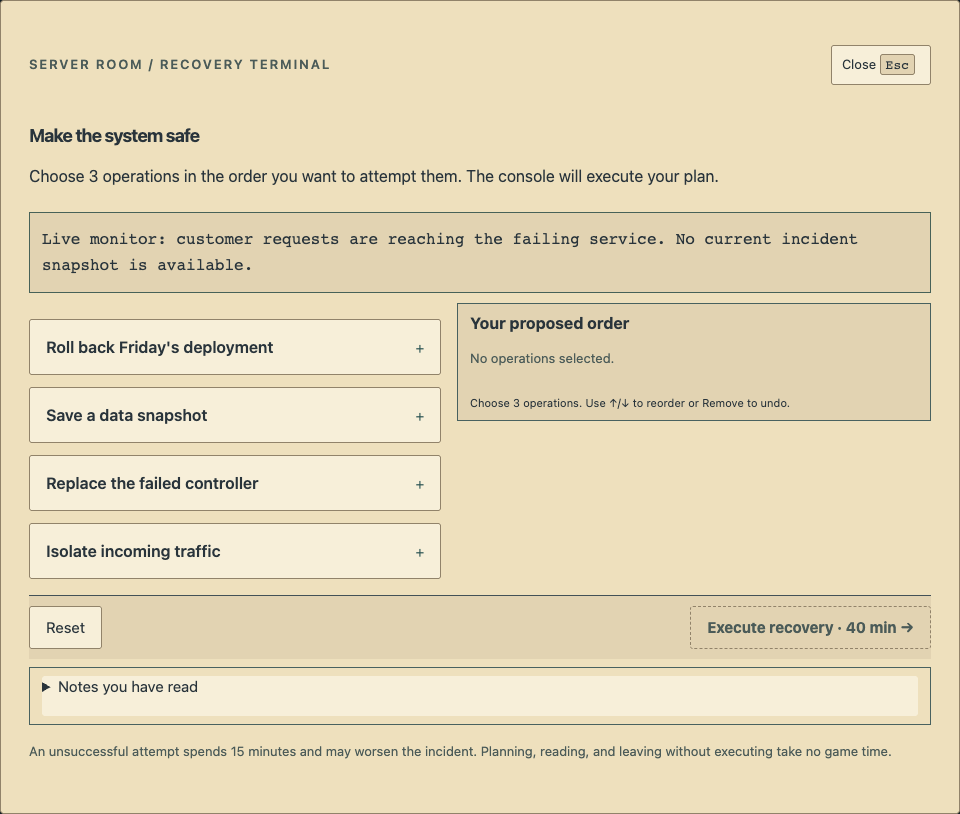
Puzzle UI: make the plan readable before executing it.
The recovery puzzle separates available operations from the player’s proposed order. These historical and current captures keep the plan empty and the notes closed. They illustrate interface evolution, rather than three different solutions or new puzzle rules. I have omitted diagnosis logs, submitted plans and revealed hints so the reasoning stays in the game.
Early / UI milestone
An empty recovery plan
Paper UI / UI milestone
The recovery workspace on paper
Latest UI / UI milestone
The current puzzle component
Evidence / Reviewed 15 October 2026
How the case study was grounded.
The prompt figures come from an existing local development audit of surviving Codex records. It deduplicates human messages and excludes machine-agent tasks from the human-prompt count. The 37-prompt figure is the distinct union of three overlapping workflow tags: bug fixing, refinement and refactoring. Classification is lexical and can miss or misclassify requests. Missing history and later development are outside that snapshot.
The revision examples come from the project feedback log, refinement notes and art review. Architecture was checked against the TypeScript simulation, React subscriptions, Phaser bridge, save migrations and bundle checks. Traversal figures come from the 15 October completion campaign’s coverage, integrity, checkpoint and replay-suite reports. Public locked labels were checked against the game’s hint registry.
Only aggregate evidence and spoiler-safe descriptions are reproduced here. Private chat transcripts, raw traversal traces, puzzle solutions, hidden conditions and real ending titles are not published.